Construction does not need more data. It needs to make better use of what it already has, argues Dr Danny Murguia of the Cambridge Laing O’Rourke Centre at the University of Cambridge
Construction organisations have spent years investing in digital tools. Projects now generate enormous volumes of information through programmes, BIM models, progress monitoring tools, labour systems, site images, sensors, delivery records and digital reports. Yet a surprisingly basic question remains difficult to answer: how productive is this project, and what does good actually look like?
This was the starting point for our research at the University of Cambridge in 2021. What we found was not a shortage of data. The problem was fragmentation. Information sat in different systems, was owned by different teams and was recorded at different levels of granularity.
Most importantly, there was no consistent way to bring it together to understand how efficiently construction work was being delivered. After five years of working with industry and analysing data from more than 25 UK construction projects, four lessons stand out.
Progress is not productivity
Construction is very good at reporting progress. We know whether an activity is 50%, 70%, or 90% complete, and whether it is ahead of or behind programme. But knowing that a project is 60% complete does not tell us whether that 60% was delivered efficiently.
Productivity requires us to ask different questions. How quickly are we producing an output? How efficiently are we using labour? At what cost? And, critically, why does performance vary?
This distinction matters because productivity should not be something we calculate retrospectively once the project is finished. It should be measured while work is being delivered, when teams still could intervene. That is one of the central ideas behind the Cambridge Framework for Construction Productivity.
Granularity changes the conversation
Project-level averages are useful, but they conceal enormous variation. A structural frame may appear to have performed reasonably well overall, while individual floors, zones, or activities experienced very different production rates, labour usage, and disruptions. The framework therefore allows productivity to be examined progressively at project, work-package, location and activity levels. Once this level of detail becomes available, the management conversation changes.
A flowline, for example, can show not simply that a structural frame finished late but how production moved through locations, where the planned rhythm broke down and where particular delays occurred.
When this is combined with consistently recorded blockers such as equipment failure, material availability, logistics, weather, design changes or rework, the team can begin to explain the deviation rather than merely report it. The aim is to move from retrospective reporting towards near-real time project control.
Every project should leave an evidence base
The second opportunity comes when data from multiple projects are structured consistently. Instead of asking, “What production rate did we assume last time?”, planners and estimators can ask, “What have comparable projects actually achieved?”
Our datasets show considerable variability even between apparently similar projects and work packages. That variability is not noise to be ignored; it is information to be understood. Benchmarks based on medians, quartiles and exemplar performance can support more defensible planning assumptions, but they also prompt a more important question: why does productivity vary?
This is where benchmarking becomes analytics. Differences in performance may be associated with crew size, crane allocation, batching strategy, construction method, logistics, sequencing, access constraints or recurring blockers to productivity.
Interrogating these factors helps organisations move beyond comparing averages and towards understanding the conditions under which stronger performance is achieved.
That leads to more useful management questions: Which factors are within our control? Which combinations of resources and production strategies are associated with better outcomes? Where are the practical productivity limits, and what would it take to move them? These are the types of questions that turn historical project data into a genuine evidence base for future decisions.
From benchmarking to prediction
Once historical project data are structured consistently, the possibilities become much broader. We can begin testing alternative production-system configurations: different crew sizes, crane allocations, construction zones or cycle-time assumptions.
Those configurations can produce very different programme outcomes. This creates the foundation for statistical modelling and machine learning that could help planners assess alternative scenarios, quantify uncertainty and understand programme risk before construction begins.
The progression is straightforward: Benchmarking tells us where we are. Data analytics begins to explain why. Predictive models can help us understand what might happen next.
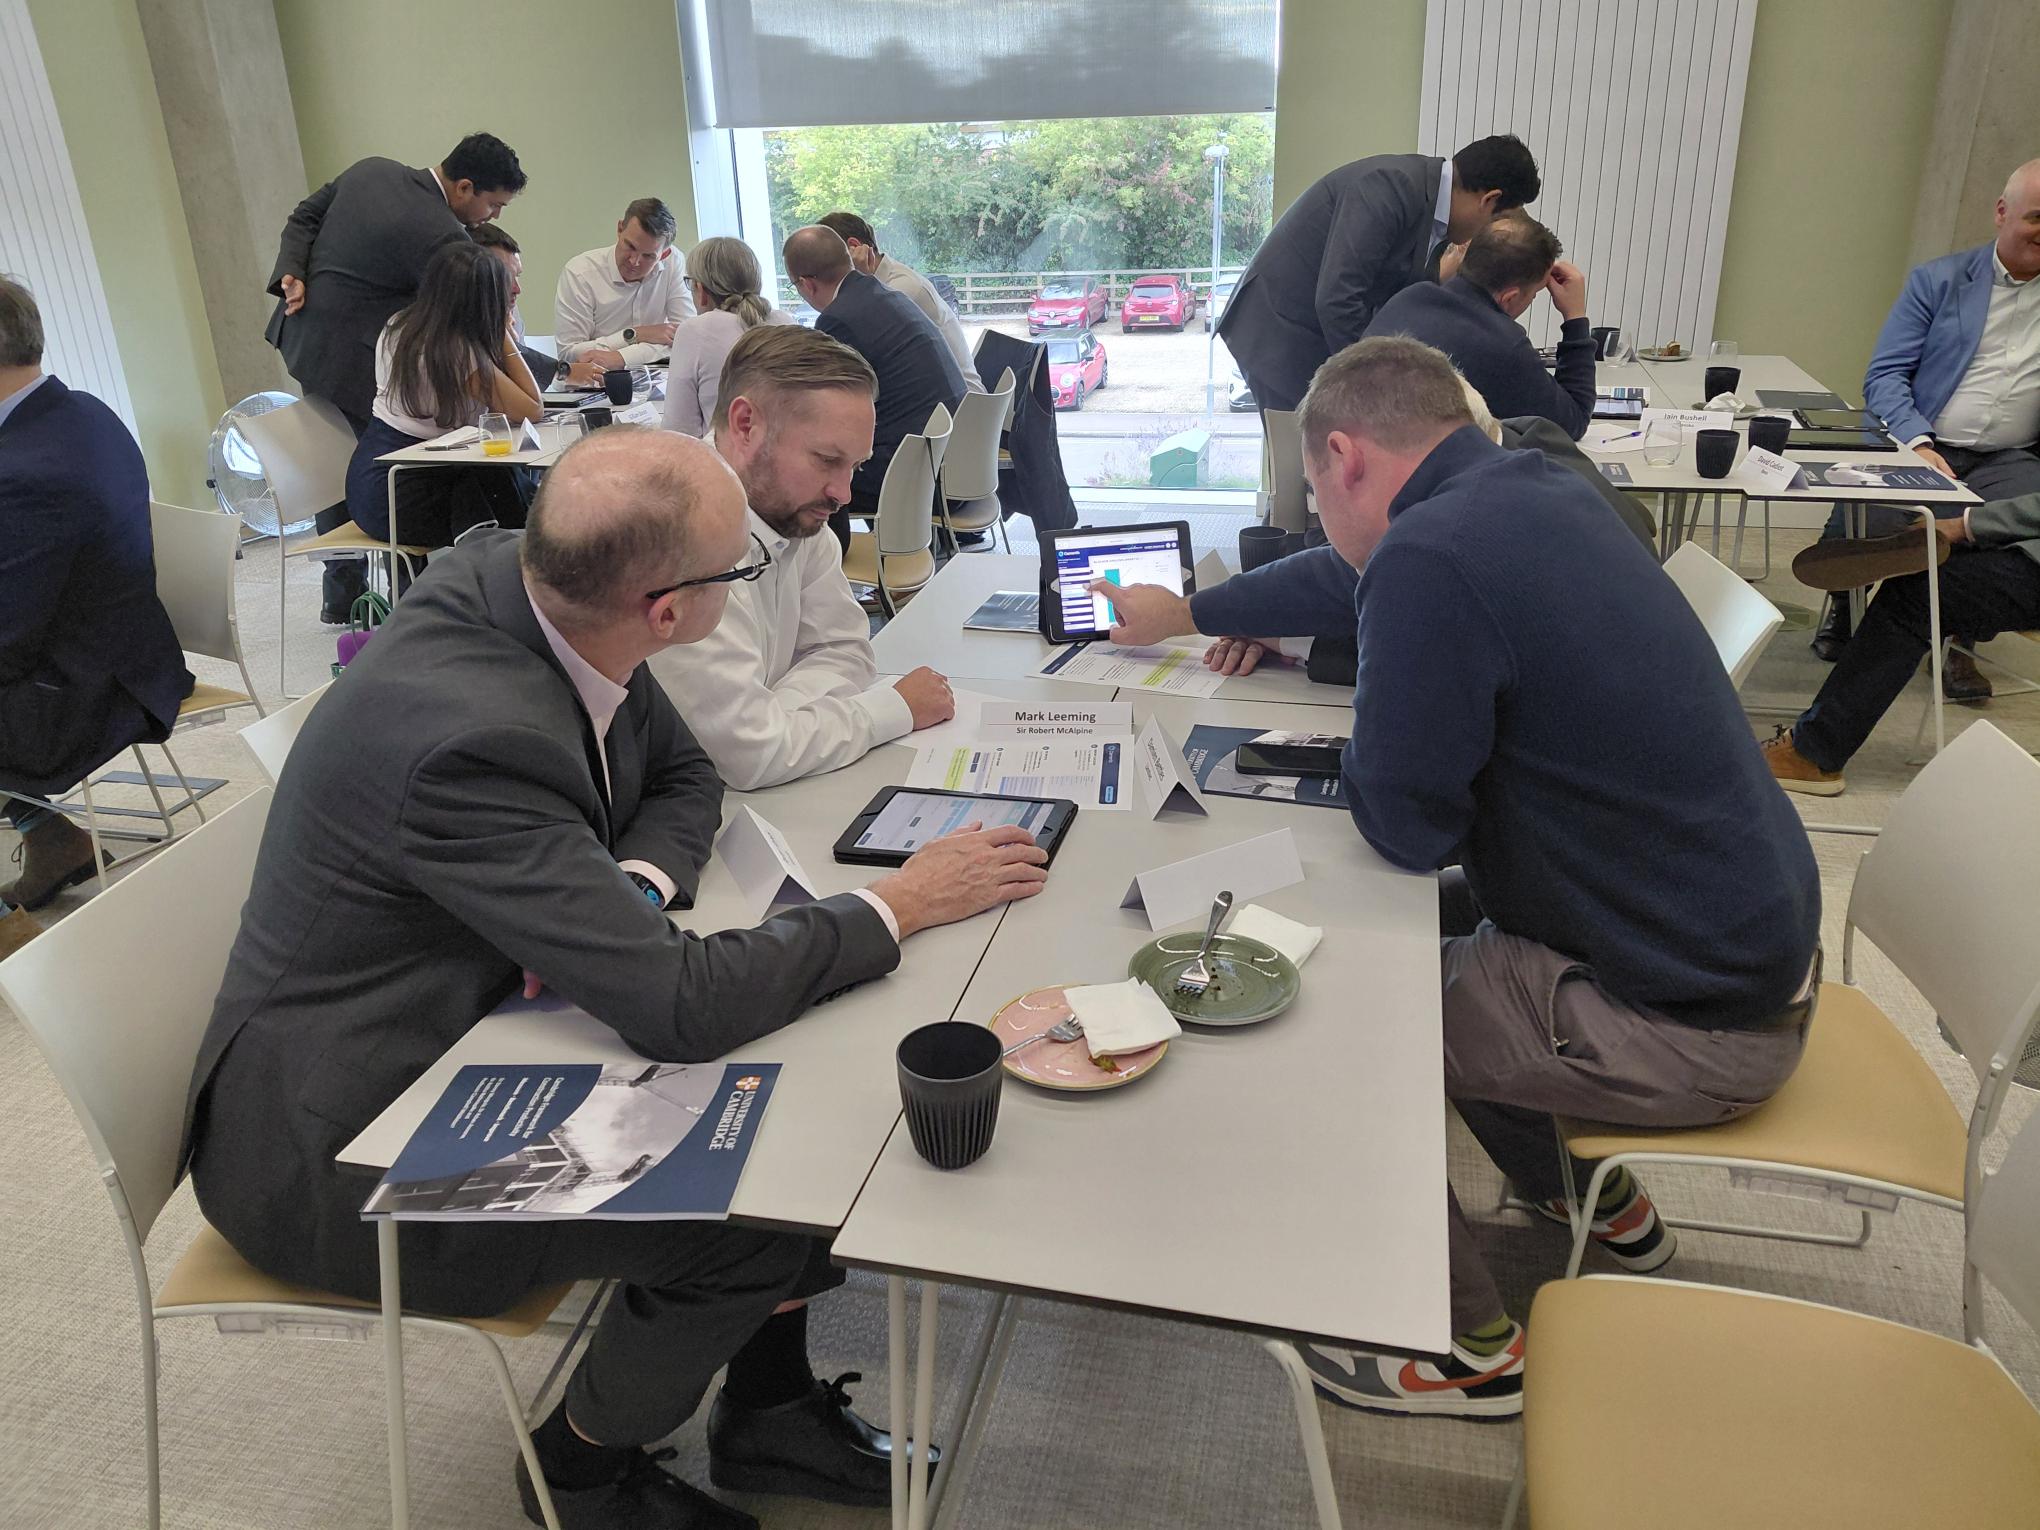
We have also translated the framework into Camentis, a software platform now being piloted on live projects, so that these principles can become part of everyday project controls rather than remain an academic methodology.
The construction industry does not necessarily need more data. It needs to measure the right things consistently while projects are being delivered, use those insights to take corrective action and retain the evidence so the next project can be planned, scheduled, priced and risk-assessed using better information than the last.
If we can do that systematically, every completed project becomes more than a delivered asset. It becomes evidence for delivering the next one better.